
I hear lots of people talking about an AMP in the creation of the documents but little about the value they add to asset management and the value an asset delivers to an organisation over its lifecycle. An AMP cannot just be another document that sits in a system, something you show an auditor, or something that gets updated once a year.
An AMP is meant to protect asset performance over its lifecycle.
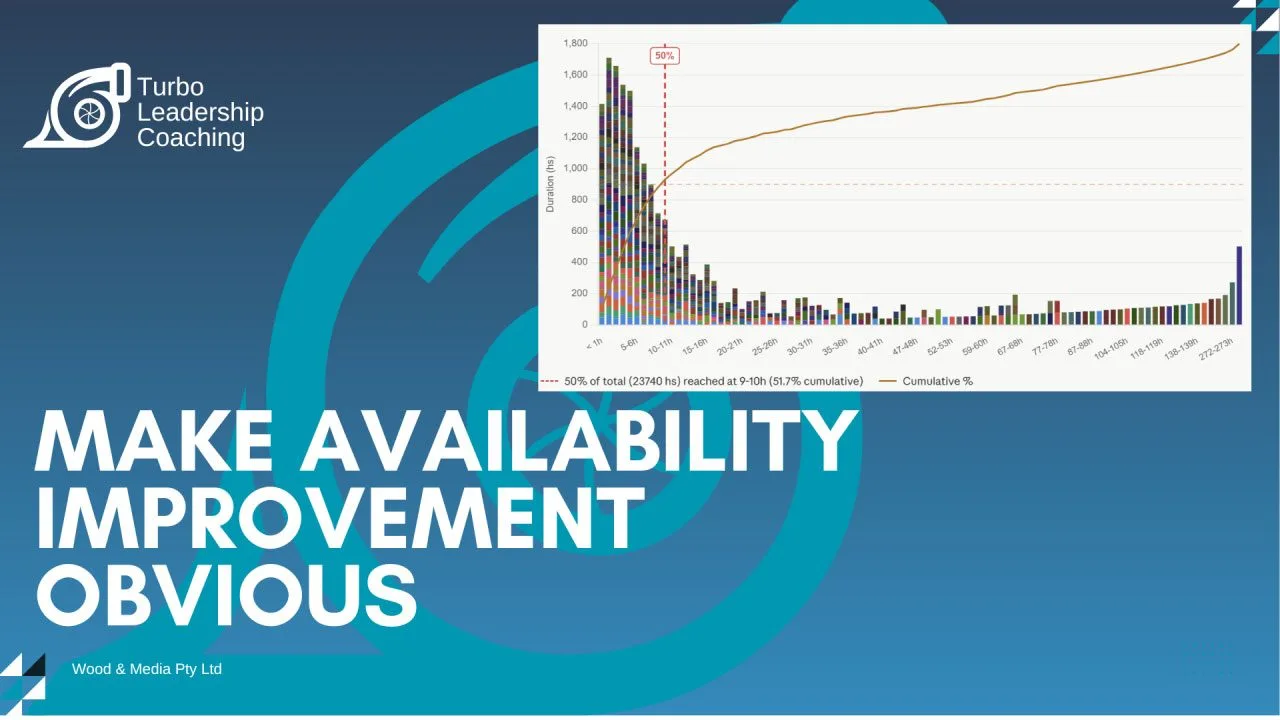
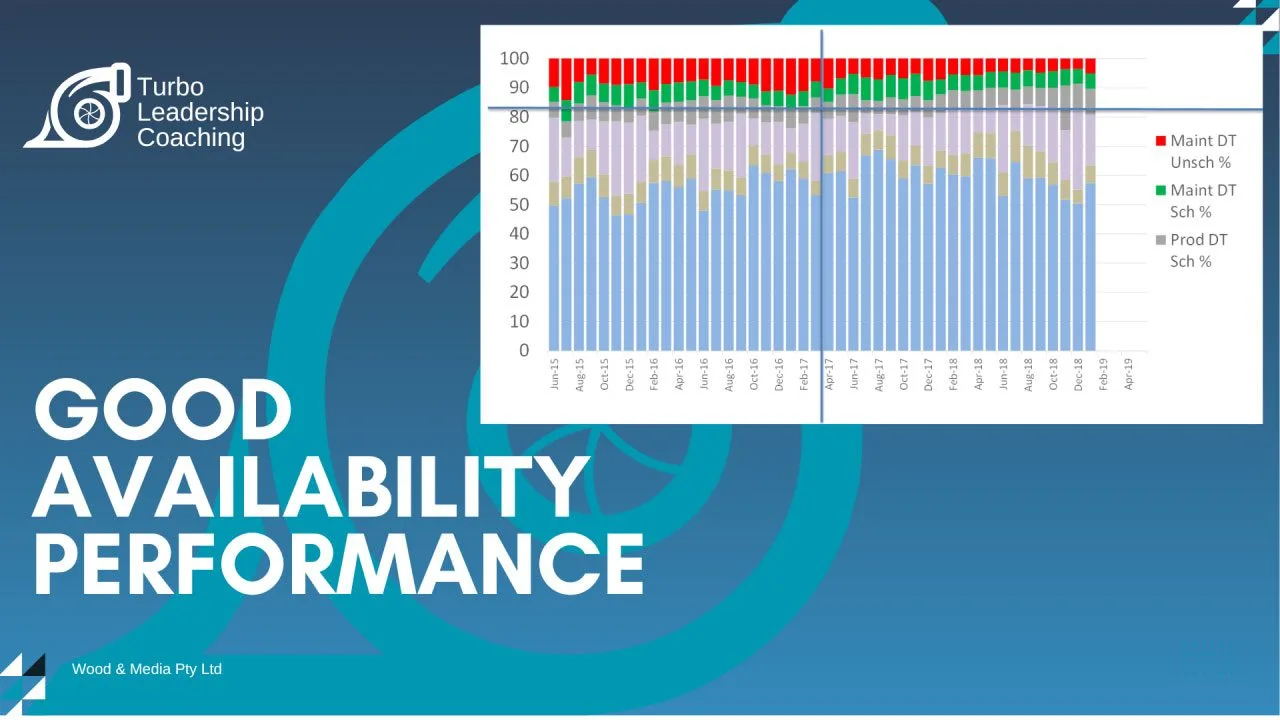
Often you walk into a site and asset performance has slipped. Availability is down, costs are creeping up, breakdowns are more frequent. Nothing obvious seems to have changed and everyone has an opinion.
But when you dig deeper, you find:
No one made a big decision, it just… happened over time.
People react to the symptoms:
But they don’t go back to fundamentals. They don’t ask: “What was the original asset management approach for this equipment and what critical practices have changed?”
A good AMP does three simple but powerful things and most importantly it helps cross functional teams align on an approach for an asset.
1. It translates strategy into action It takes high-level asset objectives (availability, cost, lifecycle) …and turns them into clear, practical expectations and practices for the maintenance and operating teams.
2. It defines the critical few practices Not everything. just the 20% of information that delivers 80% of the results. The handful of things that, if changed, will directly increase cost or downtime. In most operations, these are:
3. It highlights, not duplicates, technical detail and is not a rewrite of the asset manuals. Those documents already exist. The AMP should pull out:
At a level that is clear, visible, and usable on site so that everyone can easily align.
An AMP is not a document. It is a control system for the few practices that protect uptime, cost, and asset life. If changing something will increase downtime or cost… it belongs in the AMP. If it doesn’t influence outcomes… it probably doesn’t belong and just as importantly:
An AMP should evolve and be updated as you learn how to:
Annually you should review your compliance to the AMP, otherwise, performance can drift.
Do your people know exactly which few practices must be protected to sustain the asset performance? Could these be stated off the top of peoples heads? Could they get this information in 20 minutes by reading the AMP?… or would they be just basing an opinion on what they have seen elsewhere?